OpenAI models supports 12-hour prompt caching in API

OpenAI models now supports 12-hour prompt caching in their API. So long running agents like OpenAI’s Dots or other personal assistant which has a long running conversation don’t ended up costing us more.
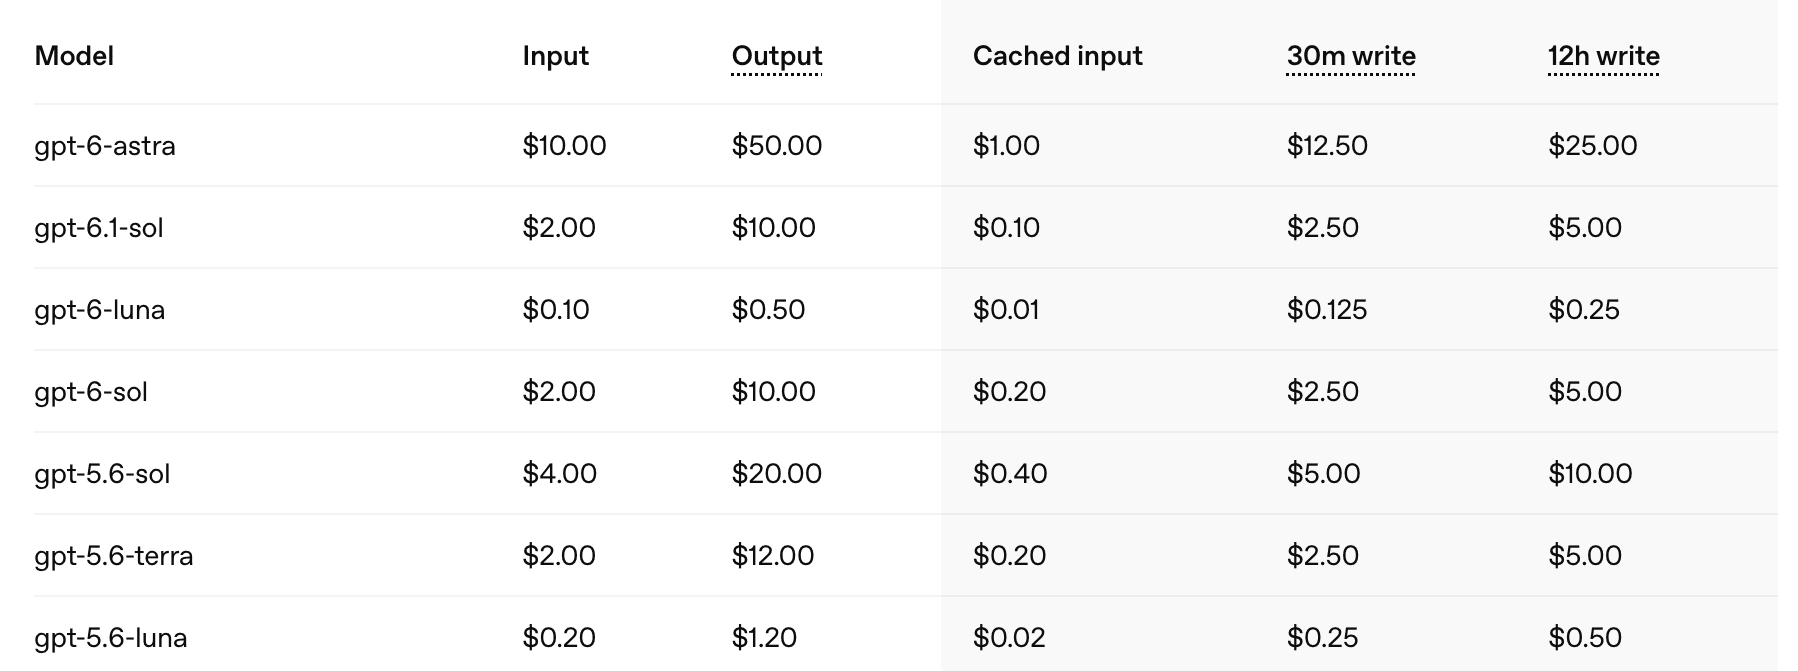
And in terms of cost it’s actually 2.5x of input token cost (whereas 1.25× for “30m”)
You can choose “12h”, keep the 30-minute default, or mix both in one request: 12h for shared instructions, 30 minutes for newer conversation content.
If you need to reuse the same context throughout the day, savings from repeated reuse can significantly outweigh the extra cost of 12-hour caching.
— OpenAI Developers (@OpenAIDevs) October 20, 2026